Selected research
Publications
Selected papers at leading international conferences in 2025 and 2026, with a focus on embodied intelligence and world models, alongside work on multimodal reasoning, agents, and foundation models. See Google Scholar for the complete publication record.
15Selected papers
06Top venues
25–26Publication years
2026
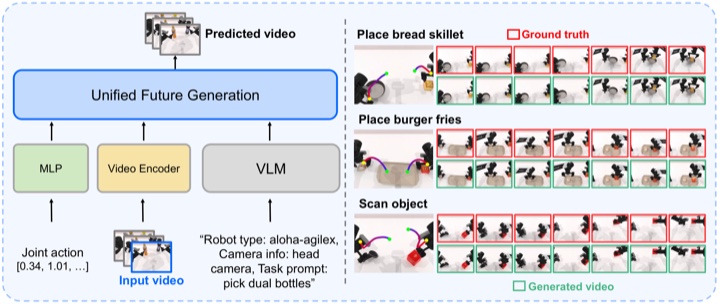
Embodied intelligence · World models
Pelican-Unify 1.0: A Unified Embodied Intelligence Model for Understanding, Reasoning, Imagination and Action
Y Zhang, Y Chen, C Liu, Z Ding, J Xu, S Zou, J Liao, J Hu, X Ren, X Zhang, et al.
arXiv 2026 · Pelican series
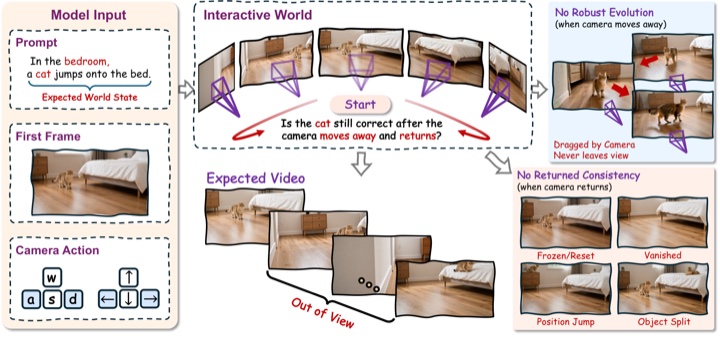
World models · Embodied interaction
Current World Models Lack a Persistent State Core
J Lu, D Zhu, H Shi, L Cai, G Tang, Y Chen, J Cao, D Tang, Y Zhang, Y Dai, et al.
arXiv 2026
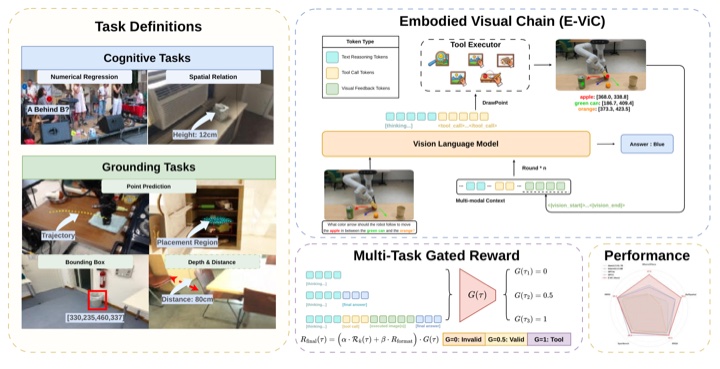
Embodied intelligence · Spatial reasoning
E-ViC: Reasoning Beyond Text via Embodied Visual Chain for Spatial Intelligence
J Qi, Y Zhang, H Ni, C Liu, Z Yao, R Yang, X Ren, L Wen, W Ge, Y Ieiri, et al.
ACL 2026
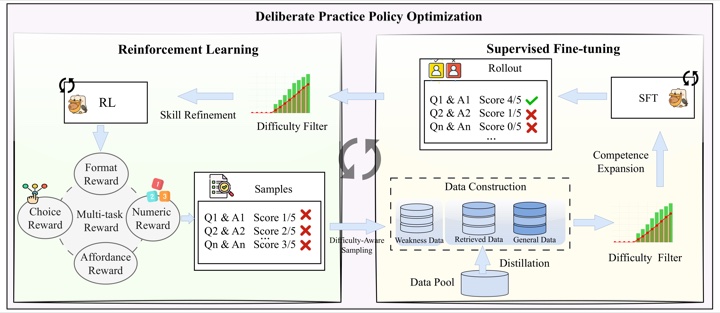
Embodied intelligence · Vision-language models
Bridging VLMs and Embodied Intelligence with Deliberate Practice Policy Optimization
Y Zhang, C Liu, X Ren, H Ni, Y Zhang, S Zhang, Z Ding, J Hu, H Shan, et al.
ACM MM 2026
Web agents · Multimodal reasoning
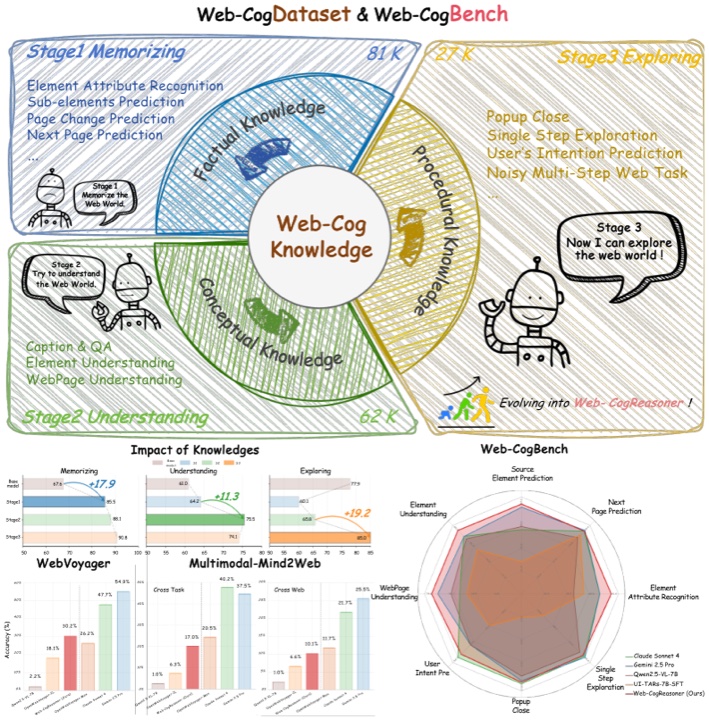
Web-CogReasoner: Towards Multimodal Knowledge-Induced Cognitive Reasoning for Web Agents
Y Guo, A Sun, H He, X Yang, Y Lu, Y Zhang, X Guo, D Zhang, J Liu, et al.
ICLR 2026
Time series · Representation learning
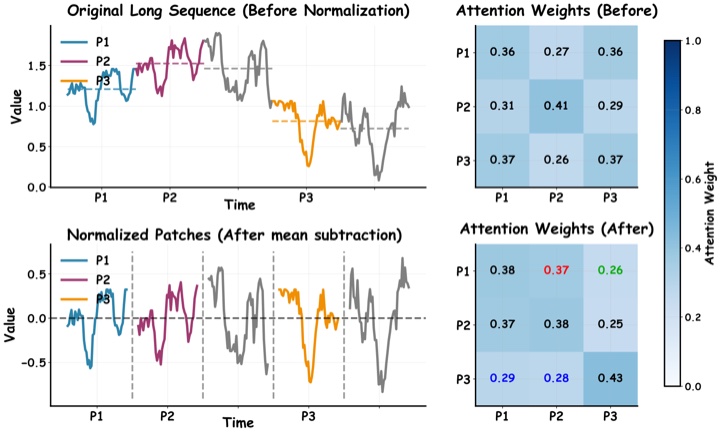
PMDformer: Patch-Mean Decoupling Information Transformer for Long-term Forecasting
A Hu, L Wen, J Duan, Y Dai, H Yan, D Wang, J Wang, R Jiang, et al.
ICLR 2026
Agentic reasoning · Retrieval
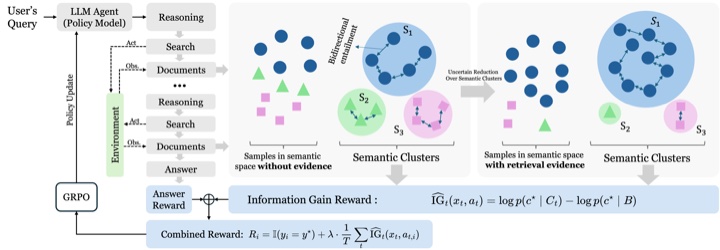
Optimizing Agentic Reasoning with Retrieval via Synthetic Semantic Information Gain Reward
S Hu, Y Dai, Y Zhao, Y Tao, Y Guo, Z Fang, STW Kwong, Y Fang
ICML 2026
Vision-language-action · Interpretability
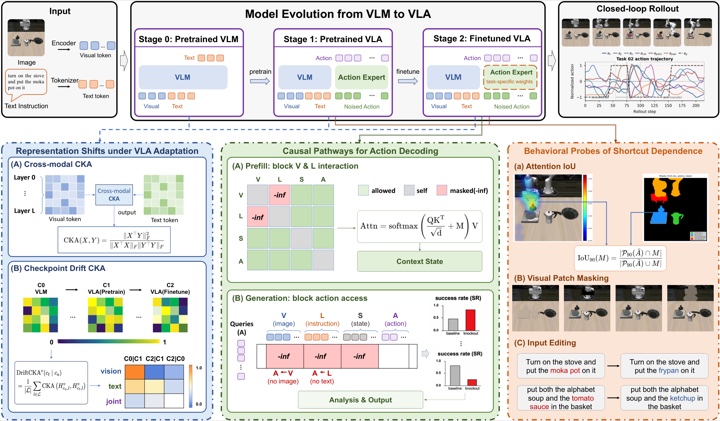
VLA-Trace: Diagnosing Vision-Language-Action Models through Representation and Behavior Tracing
H Shi, X Ren, Y Zhang, Q Zhang, J Hu, H Shan, H Dong, J Lu, Y Chen, et al.
EMNLP 2026 main
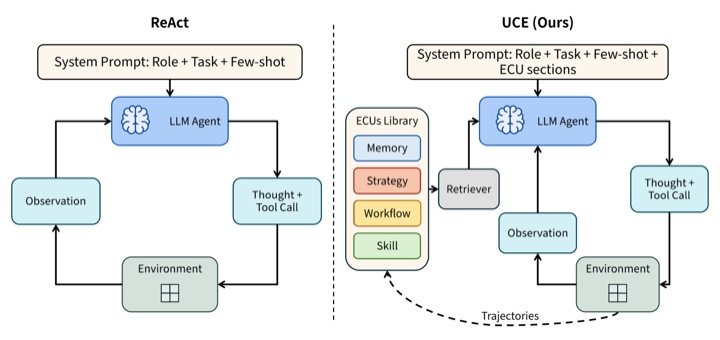
LLM agents · Context management
Unified Context Evolution for LLM Agents
Z Zhu, Y Hu, Y Dai, J Fang, C Jiang, S Hu, Y Zhao
EMNLP 2026 main
2025
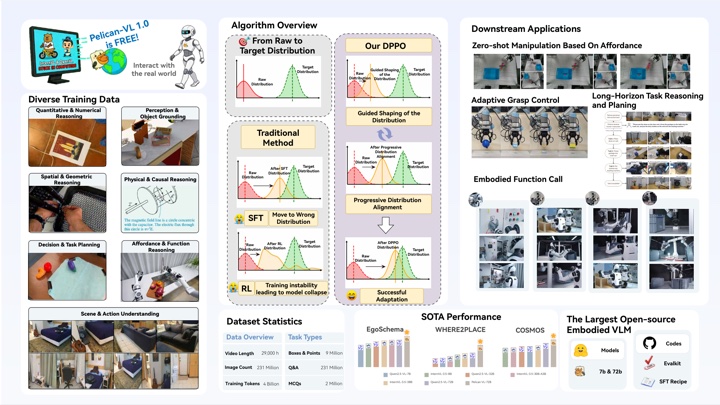
Embodied intelligence · Foundation models
Pelican-VL 1.0: A Foundation Brain Model for Embodied Intelligence
Y Zhang, C Liu, X Ren, H Ni, S Zhang, Z Ding, J Hu, H Shan, Z Niu, Z Liu, et al.
arXiv 2025 · Pelican series
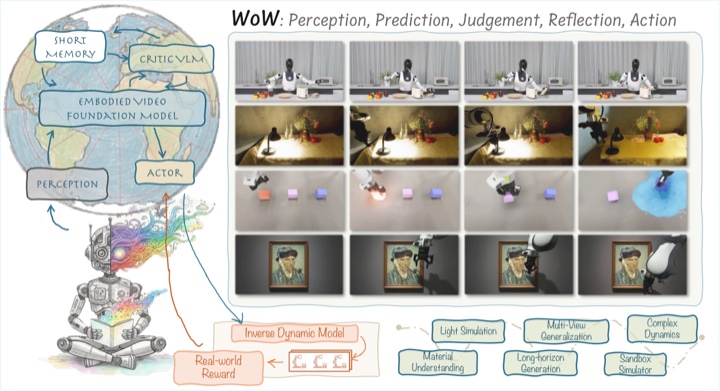
World models · Embodied interaction
Wow: Towards a World Omniscient World Model through Embodied Interaction
X Chi, P Jia, CK Fan, X Ju, W Mi, K Zhang, Z Qin, W Tian, K Ge, H Li, et al.
arXiv 2025
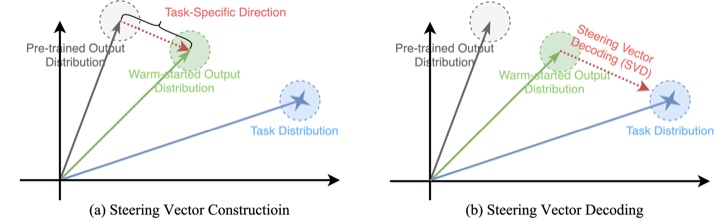
LLM adaptation · Efficient inference
Distribution-Aligned Decoding for Efficient LLM Task Adaptation
S Hu, X Han, J Jiang, Y Tao, Z Fang, Y Dai, STW Kwong, Y Fang
NeurIPS 2025
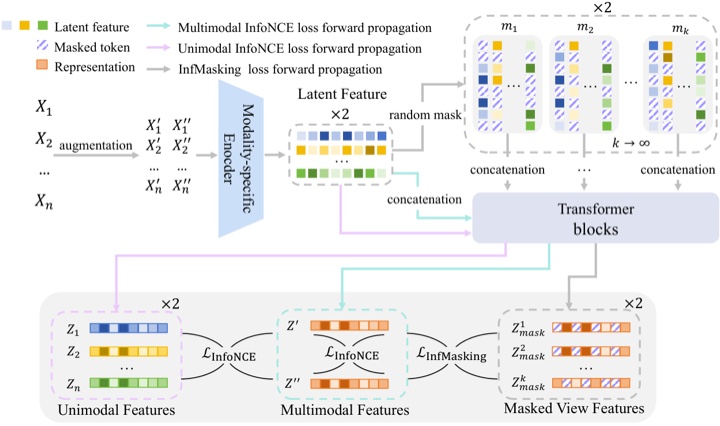
Multimodal learning · Representation
InfMasking: Unleashing Synergistic Information by Contrastive Multimodal Interactions
L Wen, Q Dai, J Liu, J Zheng, Y Dai, D Wang, Z Kang, J Wang, Z Xu, et al.
NeurIPS 2025
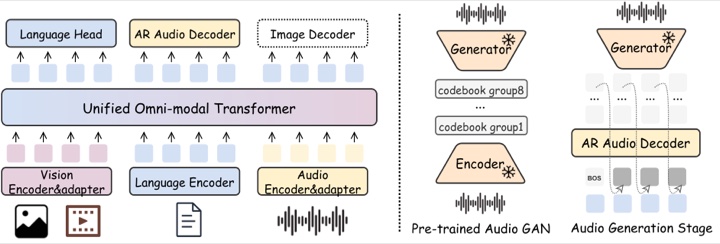
Omni-modal foundation models
Nexus: An Omni-Perceptive and Interactive Model for Language, Audio, and Vision
C Liu, Y Zhang, D Zhang, W Zhang, C Gong, H Li, Y Lu, S Zhou, Y Lu, et al.
ACM MM 2025
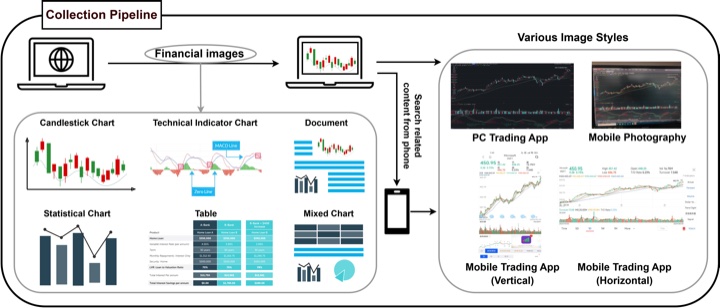
Multimodal benchmarks · Financial reasoning
MME-Finance: A Multimodal Finance Benchmark for Expert-Level Understanding and Reasoning
Z Gan, Y Lu, D Zhang, H Li, C Liu, J Liu, J Liu, H Wu, C Fu, Z Xu, R Zhang, et al.
ACM MM 2025
This page highlights recent top-conference work, with emphasis on embodied intelligence and world models. The complete publication history, citation counts, and preprints are available on Google Scholar.